The problem
Retention teams need a ranked list of at-risk customers they can trust, which means the data behind it has to be complete, de-duplicated and reproducible, and the model has to be tested the way it will be used: on the future.
Architecture
How data moves through the system, left to right.
Key decisions
A malformed upstream value is stored and inspectable, never lost at ingestion.
Spark 4's ANSI mode fails a whole batch on one bad value; try_cast turns it into NULL and quarantines that one row with a reason.
line_id hashes the whole line and the MERGE is pruned to the batch's months, so re-sent data never double-counts revenue: replaying 5 days inserted 0 rows.
Row reconciliation (in = inserted + duplicates + already loaded + quarantined), unique keys, non-null checks and share warnings, stored as a Delta table.
Train on March–July snapshots, select on August, report once on September. Deterministic training lets CI check the metrics.
Results
| Measure | Result |
|---|---|
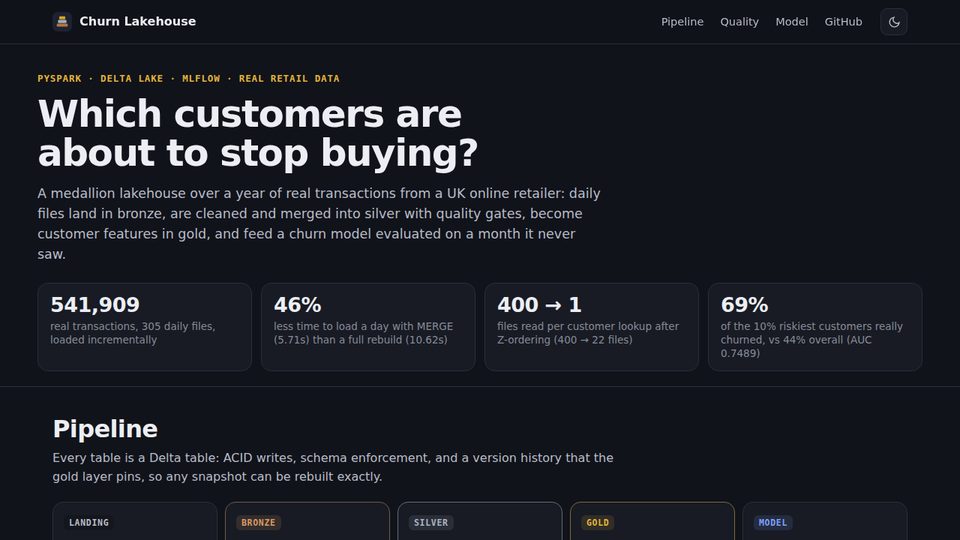
| Real transactions processed | 541,909 |
| Daily incremental load vs full rebuild | 5.7 s vs 10.6 s (46% less work) |
| Z-order: files read per lookup | 400 → 1 (5.4× faster) |
| Churn model ROC AUC | 0.749 GBT vs 0.684 recency rule |
| Precision in riskiest 10% | 69% (base rate 44%) |
| Critical data-quality checks | passed 36/36 batches |
UCI Online Retail dataset (1 Dec 2010 – 9 Dec 2011). Timings from one run on a 2-vCPU machine in Spark local mode; the Z-order benchmark uses a 20× scaled copy because 537K rows is too small for file layout to matter.
What I learned & what's next
- Gradient-boosted trees and logistic regression were within noise of each other, so the tree model's extra complexity buys little.
- Seasonality is confounded with the snapshots: churn is lowest for September, whose 90-day window covers Christmas.
- A stale Delta history metric once reported rows inserted on a replay; comparing table versions fixed the reconciliation.